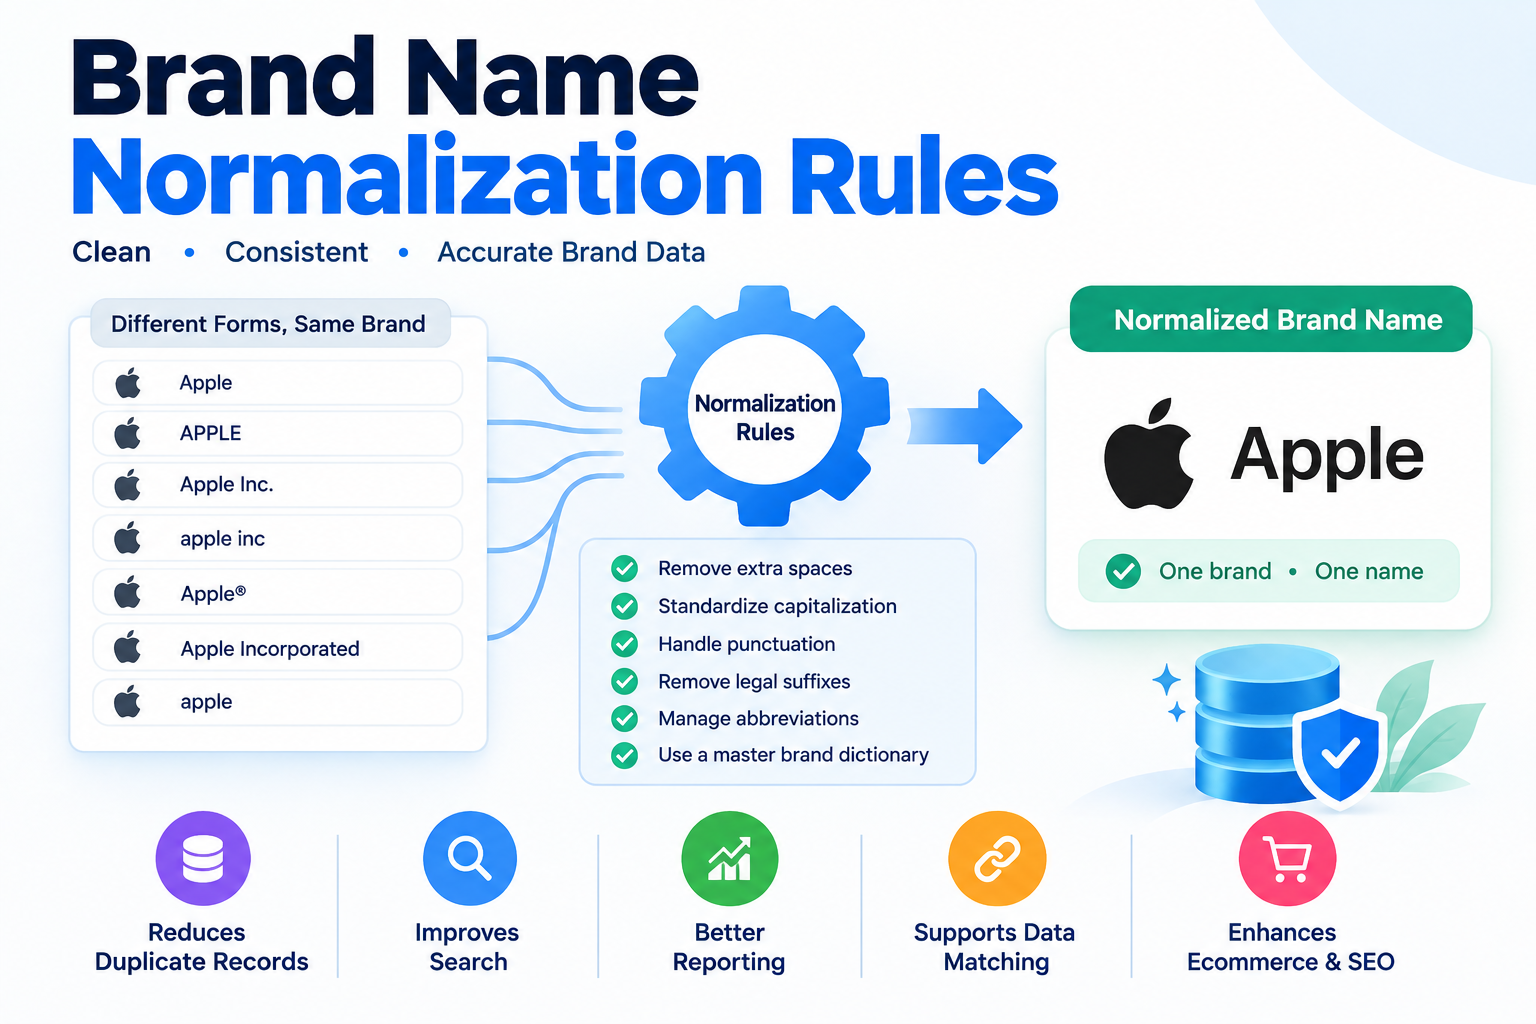
Brand names can appear in many different forms across websites, spreadsheets, CRMs, ecommerce stores, product feeds, and databases. One system may use Apple, another may use APPLE, while another may store Apple Inc.
Although these names may refer to the same organization, a computer system may treat them as different values.
This is where brand name normalization rules become useful.
Brand name normalization is the process of creating a consistent version of a brand name while keeping enough information to identify the correct company or brand. Good normalization can reduce duplicate records, improve search, make reports easier to read, and help different systems work with the same data.
For example, a business may receive these values:
- Coca-Cola
- Coca Cola
- coca-cola
- COCA COLA
- Coca Cola Company
A normalization system can map these variations to an approved canonical brand name.
The important point is that normalization should be based on clear rules. Simply changing every name to lowercase or removing every symbol can create new errors.
What Are Brand Name Normalization Rules?
Brand name normalization rules are predefined instructions that determine how brand names should be cleaned, standardized, stored, matched, and displayed.
The goal is to create a consistent representation of the same brand across different data sources.
For example:
Input variations:
Microsoft Corporation
Microsoft Corp.
MICROSOFT
microsoft
Possible canonical name:
Microsoft
The exact canonical format depends on the organization’s purpose and data policy.
A CRM may want a short company name. A legal database may need the complete registered company name. An ecommerce catalog may need the consumer facing brand name.
Therefore, there is no single normalization rule that works for every business.
A good system defines its purpose first and then creates rules around that purpose. Current guidance on brand normalization commonly focuses on capitalization, punctuation, spacing, abbreviations, legal suffixes, and a master reference list.
Why Is Brand Name Normalization Important?
Inconsistent brand names can create problems across a business.
Imagine that a sales database contains:
- Nike
- NIKE
- Nike Inc.
- Nike, Inc.
- nike
If the system does not recognize these as the same entity, reports may show five separate brands.
This can affect customer reports, product catalogs, search functions, marketing data, and analytics.
1. It Reduces Duplicate Records
Normalization helps identify different versions of the same brand.
Instead of storing multiple records for one brand, a system can map variations to one canonical record.
2. It Improves Search
Search systems can work better when brand names follow consistent patterns.
For example, users searching for a brand should ideally find products or records associated with that brand even if the source data contains different capitalization or punctuation.
3. It Improves Reporting
Business reports become easier to interpret when the same brand does not appear under several names.
Instead of seeing:
Apple
APPLE INC
Apple Inc.
apple
a report can group the records under one approved name.
4. It Supports Better Data Matching
Data from different systems often needs to be joined.
A supplier database might use one name while an internal CRM uses another. Normalization creates a common representation that makes matching easier.
5. It Helps Ecommerce Catalogs
Brand names are frequently used in product filters, catalogs, product feeds, and search systems.
Inconsistent brand values can create duplicate filters or split products between several versions of the same brand.
What Is a Canonical Brand Name?
A canonical brand name is the approved version of a brand name used as the standard reference.
For example:
| Original Value | Canonical Name |
|---|---|
| nike | Nike |
| NIKE | Nike |
| Nike Inc. | Nike |
| Nike, Inc. | Nike |
| Nike® | Nike |
The canonical name should be selected according to the business’s data requirements.
It is useful to maintain a master list containing the canonical name and its known variations.
This list becomes the central reference for future normalization.
Core Brand Name Normalization Rules
There are several common rules that businesses can use when cleaning brand data.
Rule 1: Remove Extra Spaces
Whitespace problems are simple but common.
A data source may contain:
Microsoft
or:
Microsoft
The second value may contain unnecessary spaces that are difficult to see.
A normalization process can remove leading and trailing spaces and convert repeated spaces into a single space.
For example:
Microsoft Corporation
could become:
Microsoft Corporation
This should generally happen early in the normalization process.
Rule 2: Standardize Capitalization
Capitalization is another common source of variation.
A brand might appear as:
SAMSUNG
samsung
Samsung
For matching purposes, a system can use a consistent comparison format.
However, businesses should be careful about changing the public display name automatically.
Some brands intentionally use unusual capitalization.
Examples include names such as:
- eBay
- iPhone
- adidas
A generic title case rule could change these into incorrect forms.
For this reason, a master brand dictionary is often useful. It can store the approved display form for brands that use special capitalization.
Rule 3: Standardize Punctuation
Brand names may contain hyphens, ampersands, apostrophes, periods, or other characters.
For example:
Coca-Cola
Coca Cola
Coca–Cola
A business should decide which version is canonical.
However, punctuation should not always be removed.
Consider:
AT&T
Removing the ampersand could produce:
ATT
That may not be the intended brand name.
The same applies to meaningful apostrophes and hyphens.
The better approach is to define which punctuation is meaningful and which punctuation is simply data noise.
Rule 4: Normalize Legal Suffixes
Company data often includes legal terms such as:
- Inc.
- Incorporated
- LLC
- Ltd.
- Limited
- Corp.
- Corporation
- GmbH
- S.A.
For many operational databases, these terms may be unnecessary.
For example:
Microsoft Corporation
could be mapped to:
Microsoft
However, this rule should be used carefully.
Legal names and public brand names are not always the same thing.
A legal database may need the registered company name, while a marketing database may need the consumer brand.
This is why businesses should keep legal name and brand name as separate fields when both are important.
Rule 5: Handle Abbreviations
Abbreviations can create matching problems.
For example, the same organization might appear as:
International Business Machines
and:
IBM
The system needs a documented rule for deciding whether IBM is the canonical name or whether both values should be stored separately.
Abbreviations should not be expanded automatically without a trusted mapping list.
A short form can sometimes refer to a completely different organization.
Rule 6: Remove Unnecessary Symbols
Some data sources add symbols such as:
- ™
- ®
- ©
These symbols may be useful in legal or marketing contexts but are often unnecessary for database matching.
For example:
BrandName™
could be normalized for matching to:
BrandName
However, the original value can still be retained when the exact public presentation is required.
Rule 7: Normalize Unicode and Special Characters
International brand data can contain different Unicode representations of visually similar characters.
Accented characters, apostrophes, dashes, and other symbols can create matching problems.
A normalization process should define how these characters are handled.
This is particularly important for businesses operating across several countries.
The system should avoid destroying meaningful characters simply to make matching easier.
Rule 8: Keep Parent Brands and Sub-Brands Separate
A company can own multiple brands.
For example, a database may contain:
Company A
Brand B
Product C
These values should not automatically be merged.
A good data model can store relationships such as:
Parent Company → Brand → Product
This allows businesses to report at different levels.
For example, an ecommerce website may need to display the consumer brand, while an enterprise report may need to group several brands under the same parent company.
Rule 9: Create a Master Brand Dictionary
A master brand dictionary is one of the most useful parts of a normalization system.
It can contain information such as:
| Field | Example |
|---|---|
| Canonical Name | Coca-Cola |
| Alternate Name | Coca Cola |
| Alternate Name | coca-cola |
| Legal Name | The Coca-Cola Company |
| Parent Company | The Coca-Cola Company |
| Display Name | Coca-Cola |
| Status | Active |
The dictionary gives different systems one source of truth.
Instead of creating separate normalization rules inside every application, the organization can maintain a centralized reference list.
Rule 10: Keep Original Data
One common mistake is overwriting the original brand value.
It is usually safer to keep both the source value and normalized value.
For example:
| Original Brand | Normalized Brand |
|---|---|
| APPLE INC. | Apple |
| apple | Apple |
| Apple Inc | Apple |
| Apple® | Apple |
The original value can be useful for auditing, troubleshooting, or correcting mistakes later.
Brand Name Normalization vs. Fuzzy Matching
Brand normalization and fuzzy matching are related but different.
Normalization applies known rules to clean a value.
Fuzzy matching attempts to determine whether two values are similar even when they are not exactly the same.
For example:
Coca Cola
and:
Coca-Cola
may be easy to normalize.
But:
Coca Colaa
contains a spelling mistake.
A fuzzy matching system may identify it as a possible match for Coca-Cola.
Fuzzy matching should generally be used carefully. Automatically merging two similar names can create serious data errors when two separate companies have similar names.
A safer process is:
Normalize → Match → Review uncertain records → Approve mapping
Brand Name Normalization for Ecommerce
Ecommerce websites have a strong reason to maintain clean brand data.
A product catalog can contain thousands or millions of products from different suppliers.
One supplier might submit:
Adidas
Another might submit:
adidas
Another could submit:
ADIDAS AG
If these values are treated as separate brands, the store may create duplicate filters.
Customers could see:
- Adidas
- adidas
- ADIDAS AG
instead of one consistent brand entry.
Normalization can help create a cleaner catalog and make brand based filtering easier.
Brand Name Normalization for SEO
Brand normalization can also be useful for SEO and website structure.
A website may accidentally create separate pages or categories for:
Nike
nike
Nike Inc.
Nike Shoes
These terms do not necessarily have the same search intent, so they should not automatically be merged.
The goal is to keep brand information consistent without eliminating useful keyword differences.
For SEO, businesses should distinguish between:
Brand identity
and
Search queries
A user may search for:
Nike shoes
while the canonical brand name remains:
Nike
Normalization should clean the brand entity without removing useful search context.
Brand Name Normalization for CRM Systems
CRM systems can collect data from many sources.
Customers may enter a company name manually. Sales representatives may enter another version. An imported contact list may contain a third version.
For example:
Tesla
Tesla Inc.
TESLA, INC.
Tesla Motors
A normalization process can map approved variations to the correct company record.
This can help prevent duplicate accounts and improve customer reporting.
However, historical company names require special treatment. A company may have changed its name over time, and that change can be important for historical reporting.
Brand Name Normalization for APIs
APIs often exchange data between different systems.
One API may return:
IBM Corp.
while another returns:
International Business Machines
If an application expects one exact value, the difference can cause matching problems.
A normalization layer can convert incoming values into the application’s preferred canonical format before the data is stored.
This approach can be especially useful when working with:
- Product APIs
- Supplier APIs
- CRM APIs
- Marketplace APIs
- Marketing APIs
- Customer databases
A Simple Brand Normalization Workflow
A practical normalization workflow can follow these steps.
Step 1: Collect Brand Data
Gather brand names from all important sources.
These may include websites, spreadsheets, CRM systems, APIs, product catalogs, and supplier feeds.
Step 2: Identify Variations
Find different versions of the same brand.
Look for differences in:
- Capitalization
- Spacing
- Punctuation
- Abbreviations
- Legal suffixes
- Spelling
- Special characters
Step 3: Define Canonical Names
Choose the approved name for each brand.
Step 4: Build a Mapping Table
Create a table connecting each known variation with its canonical value.
Step 5: Apply Deterministic Rules
Run basic cleaning rules such as trimming spaces and standardizing known punctuation.
Step 6: Apply Brand Specific Exceptions
Preserve special capitalization and meaningful punctuation when required.
Step 7: Review Uncertain Matches
Do not automatically merge records when the match is uncertain.
Send questionable records for human review.
Step 8: Store the Result
Save the normalized value separately from the original value.
Step 9: Monitor New Data
New brand variations will appear over time.
The normalization system should be reviewed and updated regularly.
Common Mistakes to Avoid
Brand normalization can create problems if the rules are too aggressive.
Removing All Punctuation
Removing every symbol can change the identity of a brand.
Converting Everything to Title Case
Title case does not work for every brand.
Removing Every Legal Suffix
Legal names can be important for accounting, legal, and compliance systems.
Automatically Using Fuzzy Matching
A similar name does not always mean the same company.
Overwriting Original Values
Keeping source data makes auditing and troubleshooting easier.
Ignoring Rebranding
Brands can change their names. Your master dictionary should have a process for handling these changes.
Using Different Rules in Different Systems
If the CRM, ecommerce platform, and analytics system all use different normalization logic, inconsistencies will eventually return.
Best Practices for Brand Name Normalization
A reliable normalization system should follow a few basic principles.
Create One Source of Truth
Maintain a central canonical brand list.
Separate Brand and Legal Names
Do not assume the public brand name is always the legal company name.
Keep Original Values
Store the raw source value alongside the normalized value whenever practical.
Document Every Rule
Team members should know why a value was changed.
Maintain Exceptions
Some brands intentionally use special capitalization, punctuation, or spelling.
Review Automatically Generated Matches
Automation is useful, but uncertain entity matches should be reviewed.
Monitor Data Quality
Track how many records are normalized, how many are unmatched, and how many require manual review.
Example of a Brand Normalization Table
Here is a simple example of how a normalization dictionary could look:
| Input Variation | Canonical Brand |
|---|---|
| APPLE | Apple |
| Apple Inc. | Apple |
| apple inc | Apple |
| Apple® | Apple |
| Microsoft Corp. | Microsoft |
| MICROSOFT | Microsoft |
| microsoft corporation | Microsoft |
| Coca Cola | Coca-Cola |
| coca-cola | Coca-Cola |
| COCA COLA | Coca-Cola |
The table can be expanded as new variations are discovered.
For larger organizations, this information can be stored in a database or master data management system rather than a simple spreadsheet.
Can AI Help With Brand Name Normalization?
AI and machine learning can help with difficult matching tasks, particularly when datasets contain spelling variations, incomplete information, or large numbers of records.
For example, an AI assisted system might identify that:
Microsof
could be a possible match for:
Microsoft
However, AI should not be treated as the only source of truth.
A good system can combine automated rules with human review.
A useful architecture could look like this:
Raw Data → Basic Normalization → Brand Dictionary → Matching → Confidence Score → Human Review → Canonical Brand
Simple cases can be handled automatically while uncertain cases are sent to a person.
How to Measure Normalization Quality
Businesses can track several useful metrics.
Normalization Rate
How many incoming records were successfully mapped to a canonical brand?
Duplicate Reduction
How many duplicate brand records were removed or merged?
Match Accuracy
How often does the system map a variation to the correct brand?
Unmatched Rate
How many brand values remain unresolved?
Manual Review Rate
How many records require human intervention?
These measurements can help identify where the normalization process needs improvement.
Final Thoughts
Brand name normalization rules provide a structured way to keep brand information clean and consistent across databases, websites, ecommerce catalogs, CRM systems, APIs, and analytics platforms.
The most useful rules typically cover spacing, capitalization, punctuation, abbreviations, legal suffixes, special characters, parent and sub-brand relationships, and canonical naming. Current technical guidance also emphasizes maintaining a master brand dictionary and preserving intentional brand-specific capitalization rather than relying on simple formatting rules alone.
The goal is not to make every brand name look identical.
The goal is to make sure that different versions of the same brand can be correctly identified while meaningful differences remain intact.
A strong normalization system therefore combines simple cleaning rules, a trusted canonical brand list, documented exceptions, careful matching, and human review for uncertain cases.
When implemented properly, brand normalization can give businesses cleaner data, more reliable reports, better search experiences, and a more consistent view of their brands across different systems.


